Author|Yuhang Yuan
Editor|Jingyu
The smart home community Home Assistant recently introduced a plugin called HA-Jev.
Its logic is extremely simple: it reads the power changes of the washing machine and the status of the laundry room door, then throws a question to the model, "The washing machine is done; are the clothes forgotten inside?" The model does not output any textual analysis, only returns a probability value. When the confidence exceeds 0.8, a clothing retrieval reminder pops up on the phone.
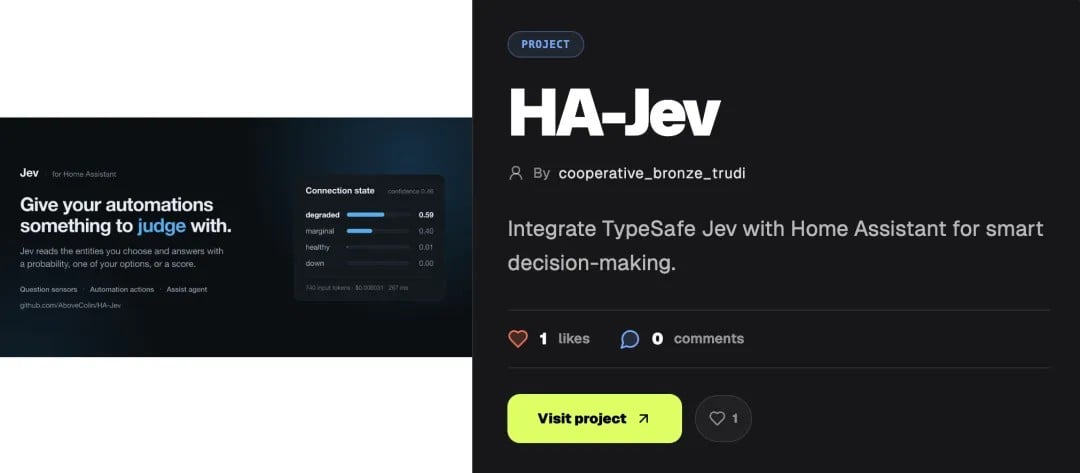
HA-Jev is only used to remind users whether the clothes washed are still in the washing machine|Image source: pitchhut
Each judgment takes dozens of milliseconds and costs $0.000015.
The plugin developer left a profound statement in the forum: "I used to use large language models to answer questions that didn't even need it. Whether clothes are forgotten is a judgment, not an article."
This statement precisely strikes at the pain point of current generative AI. For the past four years, the entire industry has compressed nearly all computing power, capital, and engineering resources into "teaching models to speak more fluent human language." Everyone has gotten used to using colossal models with tens of billions or even hundreds of billions of parameters, outputting a long string of thought processes packaged into polite and considerate natural language, and finally requiring developers to extract the desired answers using complex regular expressions.
Until former OpenAI researcher Diogo Almeida brought out his new model, Jev. This model, referred to as "System One," does not have a mouth, does not generate any text, and only outputs probabilistic judgments.
In just a few days after its launch, global developers frantically released nearly five hundred open-source projects around it. This could be the most exciting new project since Openclaw.
Everyone suddenly realized that once the expressive desire of large models is stripped away, the originally expensive and bulky AI applications suddenly become as light as a gust of wind.
01 The "Neurons" of Large Models
If we compare the past process of calling GPT-5 or Claude to hiring an all-knowing philosopher to help you monitor, then what developers are doing with Jev now resembles equipping the assembly line with countless inexpensive and responsive neurons.
In the area of agent infrastructure, which consumes the most computing power, this change is nearly disruptive.
In the past, developers handled ultra-long contexts by summarizing them with large models. Developer Tamara Tran switched to a different approach and wrote a Jev plugin to compress the context of Claude Code. It does not make any inductive summaries but scores the relevance of historical tool calls one by one, removing any lines with scores below a threshold directly.
Using the Jev plugin to compress the context of Claude Code|Image source: X
The result was extremely exaggerated; a bloated context of nearly 1 million tokens was simplified to 86,000 in just 1 second, and throughout the process, the model did not type a single character. The insight here is very simple: summarizing is an expensive generative act, but filtering is merely a cold judgment.
Similar disruptions occurred in mobile automation.
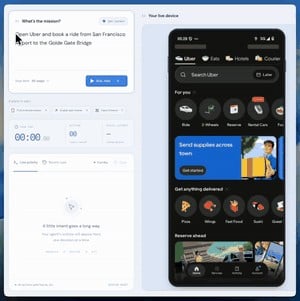
Using mobile-jev to operate a phone|Image source: jevfast.com
The Droidrun team created a mobile operating agent called mobile-jev. In a leaked demo, it controlled a real Android phone to open Uber, input the start and end points, and clicked accurately through to the payment interface, completing 9 operational steps in just 21 seconds.
The entire process did not call any traditional text-generating large models; the text input was directly extracted from the user commands as pure text fragments, and every next step on the interface—where to click, where to swipe, or where to confirm—was all handed to Jev for rapid probabilistic matching.
In addition to operating interfaces, developers even integrated it into the oldest infrastructures.
Soon, pg-jev and duckdb-jev appeared on GitHub. Developers began using natural language to perform real-time probabilistic filtering and sorting of database row data. In the Ruby community, someone even encapsulated judgments into native control flow syntax, making the code look like it endowed the program with intuition.
Using Jev to play "StarCraft" has become a series of GitHub projects|Image source: Github
In the gaming sector, some have let Jev control emulator states to play Super Mario, others have used it to drive the guards in Doom, and even a team has integrated it into StarCraft to complete the first combat mission. Games require operational decisions within tens of milliseconds, while previous large models couldn't even sort out their thoughts for the first frame before the game character was already defeated.
Even in data cleaning tasks that are considered dirty and tedious, the gap is shockingly large.
A developer had three months of backlog product matching data, totaling 9,081 entries. Back in June, he calculated it using mainstream large models, but the high API costs led him to give up entirely. After switching to Jev, he wrote 150 lines of scripts in one night, completing the entire task in 13 minutes, with a total invoice of only 32 cents.
When large models no longer pretend to be learned human beings, AI can truly embed itself into the capillaries of automated software.
02 The Jevons Paradox
The name Jev is taken from the 19th-century British economist William Stanley Jevons.
The famous "Jevons Paradox" in economics states that when advancements in technology improve the efficiency of a certain resource leading to a significant decrease in its usage costs, the total consumption of that resource not only does not decrease but instead shows explosive growth.
TypeSafe AI has set the price for Jev at only $0.042 per million input tokens, with output being free. According to this pricing, conducting 10,000 business decisions a day would cost around $120 per month. In contrast, if using a comparable high-accuracy top reasoning large model for the same processes, the monthly bill would rush towards $35,000.
The plummeting costs have instantly activated those previously deemed "commercially worthless" marginal scenarios.
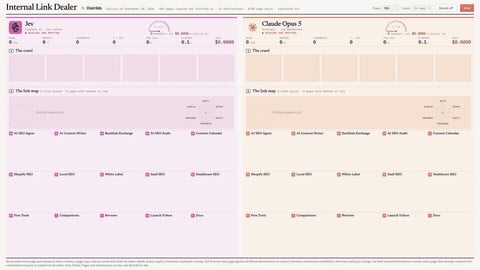
Using Jev for SEO is astonishingly fast|Image source: X
In the field of content analysis, the founder of Distribb used Jev to scan nearly six hundred web pages, completing the reconstruction of the internal linking map in 45 seconds, laying out over five hundred links, costing a total of 21 cents. In the past, using a top large model for this task would not have completed even twenty pages in the same amount of time.
The founder's reflection hit the essence: "This is not content creation; it's just 8,790 decisions on whether to link or not."
This also explains why founder Diogo Almeida left OpenAI with a sigh, "We hold a lightning bolt in our hands, but it's not that easy to use."
As a core researcher involved in building ChatGPT and jointly inventing RLHF, Almeida's reflection carries a coldness of an industry insider. In his view, the entire industry has been stuck in the dead end of "optimizing human natural language" for too long.
Collaboration between computers does not need rhetorical flourishes; machines require clear instructions and probabilities. The language capabilities painstakingly crafted over the past four years with hundreds of billions of dollars are often inefficient hindrances in the face of serious system engineering.
The CTO of the Pi framework, Armin Ronacher, candidly discusses this phenomenon: "We should have realized this a long time ago. Just because mainstream large models were subsidized by venture capitals to an extremely cheap degree, everyone got used to squandering, and no one was willing to engage in true creative thinking."
Once this illusion of cheapness is broken, the shift in architectural design will be irreversible.
Large models are retreating to where they originally should be.
They should not act as central processors; they are more suitable to serve as front-end public relations spokesmodels. In the future system architecture, massive milliseconds-level judgments will be entrusted to intuitive models as cheap as tap water, and only at the very few nodes where it's truly necessary to output segments of text to human users, provide emotional value, or draft complex lengthy reports, will the costly generative model be awakened.
03 The Separation of "Judgment" and "Generation"
Looking back at the AI narratives of the past three years, the main theme has always been "larger, smarter, and more versatile large models." A model that can chat, write code, analyze images, and do everything. The entire industry assumed that "intelligence" is a solid block that cannot be disassembled.
The emergence of Jev has shattered this solid block. It proves that some tasks require reasoning and expression, while others only need quick judgments. Binding the two together is a structural waste.
The popularity of Jev has ignited enthusiasm in the open-source community|Image source: Google DeepMind
Just one day after Jev's launch, the open-source community has already followed suit. Contributors to vLLM quickly created an open-source version using Google's DiffusionGemma, with preliminary tests showing accuracy close to the official version. This indicates that "judgment models" have established themselves as a category, and not merely as a product innovation from one company.
More notably is the change in downstream architecture. In the paradigm catalyzed by Jev, an AI system no longer has "one brain" but instead begins to show division of labor: massive milliseconds-level judgments are given to intuitive models as cheap as tap water, and only at the very few nodes where outputting segments of text to human users or drafting complex documents is truly necessary will the expensive generative model be awakened.
This is not cost reduction and efficiency improvement; it marks the beginning of AI infrastructure transitioning from "centralized" to "distributed division of labor."
When the cost of a judgment drops from several cents to one ten-thousandth of a cent, developers are not just making the original 100 judgments cheaper. They begin to make 10,000 judgments they would never have made before. Adding a semantic filter to each database record, adding a safety review to each tool call, adding a judgment of "Are the clothes forgotten?" for the washing machine.
These are not optimized versions of existing tasks, but entirely new intelligent consumption scenarios.
So, what innovations will you use Jev for?
免责声明:本文章仅代表作者个人观点,不代表本平台的立场和观点。本文章仅供信息分享,不构成对任何人的任何投资建议。用户与作者之间的任何争议,与本平台无关。如网页中刊载的文章或图片涉及侵权,请提供相关的权利证明和身份证明发送邮件到support@aicoin.com,本平台相关工作人员将会进行核查。


