(Click to listen to this episode👆)
Interview | Yiwen, Hongjun
Text and images | Yiwen
How can we use limited money to help more people? Effective Altruism (EA) starts from this simple question, encouraging people to compare the effectiveness of different charitable projects, from donating mosquito nets and preventing malaria, to later investing hundreds of millions in AI safety research.
The collapse of SBF and FTX once plunged this movement into a credibility crisis. Recently, controversies sparked by AI researchers resigning, safety assessment agencies, and donation networks have once again brought EA into the spotlight. How do the judgments of some who view preventing AI from destroying humanity as the most worthwhile cause affect the direction of research and funding allocation? What interests and power issues are involved?
In the first part of this episode, we explored through technology journalist Afra's perspective how EA gradually influenced today’s AI research, funding flows, and even political agendas, stemming from a discussion about "how to do good more effectively." The impact of these ideas today would not be possible without the substantial financial support behind them.
In the second part of the program, Silicon Valley 101 spoke with one of the important donors—Vitalik Buterin, co-founder of Ethereum. In 2021, he donated a batch of cryptocurrency to multiple charitable organizations for pandemic relief, global health, and research, among other fields. According to his recollection, part of the donation to the Future of Life Institute (FLI) amounted to about 400-600 million dollars. FLI has also clearly stated that Vitalik is their largest donor to date. However, FLI’s focus has since shifted: from researching areas combatting existential risks for humanity to a full commitment to AI safety and increasingly moving toward policy actions.
In the program, Vitalik told us that he attempted to communicate with FLI, hoping they would broaden their focus, but FLI refused, which became the starting point of their divergence. He believes that EA's ideas are very effective in the realm of man versus nature, but the situation becomes much more complex when it enters the realm of man versus man.
Vitalik argues that there is still great uncertainty regarding whether AI poses a risk of destroying humanity; people with different stances question the safety philosophy of Anthropic, and even within EA, there exist groups that support and oppose Anthropic. In the face of technological advancement and various unknown risks, he has summarized a set of d/acc (defensive accelerationism) ideas, advocating for the priority development of technologies that protect people and decentralize power, such as cybersecurity, vaccines, and air filtration, to improve society's ability to withstand risks.
We welcome you to follow the “Silicon Valley 101 Video Channel” oraudio programsto directly receive this episode's podcast. If you enjoy our show, we recommend using an audio client for listening. “Silicon Valley 101” is available on major audio platforms (channels listed at the end of the article), and subscriptions are welcome!
Here are some highlights from this conversation:
Yiwen:What initially drew you to EA? What captured your interest at that time?
Vitalik: The first time I heard of the concepts of rationalism and EA was probably between 2013 and 2015, back when both were still in their early stages. Eliezer Yudkowsky was associated with rationalism; he had a blog called LessWrong, where he wrote many articles known as The Sequences (series articles), discussing all sorts of interesting topics related to physics, ethics, and more.
There exists a group of effective altruists who mentioned: Most charitable actions we partake in are well-intentioned, yet their efficiency is generally very low. At the time, they were discussing many health issues in Africa, and they had a famous statistic: If you provided $2000 to buy mosquito nets for some very poor countries in Africa, you could prevent many people from getting malaria, every $2000 you spent could save a life.
If this is truly the case, then I too must spend my money in such ways. Between 2016 and 2017, Ethereum rose tenfold, so I sold a small portion of my Ether to donate to those organizations.
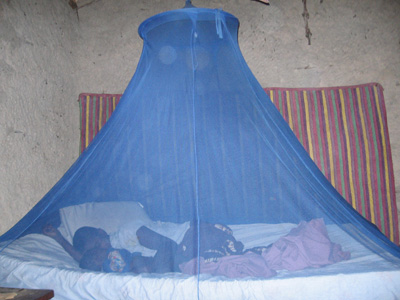
Drug-treated mosquitonets are one of the most effective interventions against malaria globally and signify EA’s “mosquito net period.” Image source: President's Malaria Initiative (public domain)
Yiwen:When you started paying attention to EA, what were your thoughts on AI safety? When you were donating or engaging with some organizations, what was their level of involvement in AI safety like at that time?
Vitalik:At that time, my thoughts on AI safety were still quite abstract. I knew that AI was theoretically a significant topic; what they said could be true, and AI safety could indeed determine humanity's future. However, regardless of whether this possibility was 100% or 0.1%, there were very few people thinking and researching these topics back then.
In 2015, the AI we now discuss barely existed. The AI we were worried about by 2018 might have been camera systems and AI-assisted digital surveillance. Between 2020 and 2023, when GPT-3 came out, everything changed significantly; AI became a real topic. When ChatGPT emerged, we began to understand that AI might develop very rapidly, bringing about many changes in our lives.
Before 2022, the only answer was how to help research more so that humanity knows more, which was better for us. But after 2022, it transitioned from an abstract topic to a concrete one.
Hongjun:Do you worry about AI safety?
Vitalik:When people ask me about P(doom) (the probability of human extinction)—whether AI or other risks could completely destroy our world, making humanity non-existent—I would say 0.1. Why do I say 0.1? Why not 0.03? Why not 0.3? In fact, it’s tough to specify more precisely because I started with a lot of uncertainty and many unknowns.
First, how quickly will AI develop? Perhaps reaching so-called AGI will take 10 years, or possibly 300 years.
Second, is the alignment problem (the alignment issue) Yudkowsky mentions truly a problem? Will this issue resolve itself simply? For instance, let’s say we create a very intelligent AI, and we tell it we want a world without cancer; it could think the simplest solution is to destroy the entire world and kill everyone. Actually, if you talk to Claude or GPT or modern AI now, you realize today’s AI is better at understanding context and our meanings—that’s a change that was quite hard to predict ten years ago.
However, that doesn’t necessarily imply that the alignment problem isn’t a significant issue. If you now ask Yudkowsky: Look at today’s AI; if you tell them to cure cancer, they won’t completely destroy the world; does that mean the alignment issue is solved? He would say: No, it doesn’t. This issue is just a small part of the alignment problem; there are many other aspects, and many risks we haven’t solved or even identified yet. The uncertainty here is substantial.
Third is the uncertainty in politics. Several countries, people, and companies are developing AI right now. In a competitive scenario, there are differing objectives; everyone hopes for safety while also wanting to win. For example, if AI becomes very dangerous and a third world war breaks out at the same time, the greatest danger may not be due to technical problems, but because during that time, everyone might primarily think "winning is what matters," with safety being a secondary concern.
So we face the uncertainty of technology, multiplied by the uncertainty of other technologies, multiplied by political uncertainties, and more and more. Whether AI truly poses a danger to us is incredibly hard to predict.
Hongjun:I noticed that on May 12, 2021, you made many donations to EA organizations; in 2017, you donated to the Machine Intelligence Research Institute (MIRI) created by Yudkowsky and others. Can you talk about what you were thinking when you decided to make those donations on that day in 2021? What guided you in making those decisions?
Vitalik:This story is quite interesting. In 2020, Dogecoin became extremely successful, and everyone started launching their own Dogecoin, with the largest being Shiba Inu (SHIB).
The official logo of Shiba Inu coin (SHIB), created in August 2020 with a total supply of 1 quadrillion; in early May 2021, Shiba Inu’s price surged, attracting market attention. Image source: shib.io
They also did something fun: they put half of their coin's supply in my wallet. It was still during the pandemic, so I didn’t do much for a long time. But one day I found that the market value of those coins had reached eight billion; it was truly outrageous. So I decided: well, they might become affluent within a week, but that bubble could burst in a week, and they may drop significantly thereafter.
I conducted a lot of complex operations to extract those Dogecoins; initially, I quickly sold them for Ether, earning around 70 million dollars’ worth. I donated most of this to the Against Malaria Foundation (AMF), the organization that buys mosquito nets. This money was quite possibly the most I could contribute, so it should go to a relatively safe and uncontroversial organization. I also donated to some other longevity (health) organizations.
Due to limited market depth, I lacked the liquidity to sell that much Dogecoin, so after converting it to Ether, I still had a considerable amount of Dogecoin left. I decided: well, these coins might drop rapidly and significantly, but I will donate the remainder to other organizations I feel are good; if they can get something when they sell it, that would be great. In my mind, they would at most get about 20 million dollars.
So I gave half to a COVID relief organization in India called CryptoCOVID Relief and the other half to FLI (Future of Life Institute). FLI was at the time a research organization starting to combat all existential risks. They studied every major risk, such as biological, AI, and nuclear war-related risks. They introduced me to a plan, telling me that theoretically, they could reach up to one hundred million, but even twenty million could do a lot. So I said, okay, I’ll give you my Shiba Inu coins.
Three months later, I found those Dogecoins didn’t drop. The first organization, CryptoCOVID Relief, sold off these coins and raised 470 million dollars. I’m not sure how much FLI received, but it could be four hundred million or six hundred million.
Completely beyond my imagination; had I predicted such outcomes, I would have acted entirely differently. So the next year, I chatted with Sandeep from the CryptoCOVID organization, and convinced him to return half of his money to me, after which we began some pandemic-related work, including researching filters, UV light, masks, and long Covid studies; we donated to open-source vaccine companies, one being RADVAC (an open-source nasal spray vaccine project) and another being PopVax (an Indian biotech company).
By early 2022, everyone thought COVID was over, so we began combating all airborne transmissible diseases. We utilized two hundred million to achieve significant results. Sandeep used his 270 million, which could be said to have upgraded India’s entire medical manufacturing capabilities.
About this time, after the emergence of GPT-3, FLI underwent a major shift in thought. First, they shifted from caring about all existential risks to focusing solely on AI; second, they transitioned from a research attitude to a political action stance. They began to adopt concrete strategies, contemplating which laws to support and which politicians to back. They started taking many actions that I either did not agree with or would not fund personally.
I communicated with them two or three times and expressed that my original objective was to support all domains countering existential risks; I wished for them to broaden their scope. However, they refused, choosing to channel all their funds toward an AI-centric and policy-focused direction. At the same time, the laws they advocated began to emerge; many a16z and Silicon Valley investors were quite unhappy and began viewing AI safety as their main adversary, which started around 2023.
Hongjun:Do you feel your ideas have changed regarding how to donate and how to approach donations? Including, we’ve also seen the world changing after these donations—AI is rapidly advancing, and the direction of their invested funds diverges from the initial goal of curing diseases in Africa.
Vitalik:I believe one important concept in EA is neglectedness (the degree of neglect), meaning: Is anyone else already working on it? About ten years ago, I believed every field related to EA and rationalism was very neglected.
But that is not the case now. Today, AI safety is a high-profile topic, as is longevity and health. Furthermore, global public health suffered significantly in 2025—as a result of actions by Elon Musk and political shifts in the US that previously supported many public health-related projects but quickly stopped, leading to more problems. Thus, I think global public health has become more important; it is an area worthy of support.
However, most other fields are not neglected. It's not due to insufficient resources, but because the methods employed are flawed, and the required solutions vastly differ. Solving these problems is no longer a research issue; it has genuinely become a policy issue. Yet, the challenge with policy issues lies in their complexity; it’s difficult to ascertain whether a policy is good or bad. Therefore, the nature of policy issues is considerably different from what earlier EA thinkers pondered.
Previously, EAs would often consider: If you donate to organization A, you might save 10 lives; if you donate to organization B, you might save 100 lives. Your challenge is figuring out which is which. But now, it’s entirely different because you’re supporting a policy, and that policy may yield positive or negative effects, with no certainty about which outcomes will be favorable or harmful; it's quite complex.
This policy has some direct effects in how it impacts company incentives; it also has indirect ones. For example, if a wealthy person publicly spends 500 million supporting certain political topics, others might be discontented, feeling “a billionaire is influencing our politics,” and they might perceive the AI safety agenda as something only rich people think about. This could lead to more people opposing AI safety.
This is a man versus man (human against human) issue, extremely complicated because the challenges faced are against equally intelligent opponents. I think the ideas of EA work wonderfully in areas of man versus nature, but when it comes to man versus man, it becomes considerably more complex.
Hongjun:To summarize, there are a few major factions in Silicon Valley: EA, rationalism, and those represented by Andreessen Horowitz (a16z), which is AI accelerationism. These three factions are currently the primary ones regarding AI. And your d/acc.
Vitalik:I might say: First is the EA that supports Anthropic; second is EA more distanced from Anthropic; thirdly, there’s PauseAI (“Pause AI” movement). PauseAI leans more toward populism; they are more willing to collaborate with mainstream individuals and more willing to assert that all rationalism and AI are detrimental. Fourth is e/acc, including Jeff Bezos and a16z.
The position of rationalists is quite interesting presently. Many of them have very different thoughts, but they feel they are similar to EA—though there are many crucial differences. If you see rationalists today and some news, the disparity is pretty significant.
Hongjun:You just mentioned there are EAs supporting Anthropic and opposing Anthropic; can you expand on this? What distinctions in viewpoints exist between these two groups?
Vitalik:The EAs who support Anthropic argue: AI is very dangerous, but it is impossible not to pursue AI because there are many teams, companies, and countries worldwide. Thus, the only way is: if a company has good people, that good company should prevail. Because when they succeed, they will at least have better principles; in times of greatest need, they will dedicate more effort to ensure AI is developed responsibly. You could even argue that Anthropic embodies better practices than OpenAI, as you see the internal conflicts that arise at OpenAI and what the thoughts and mindsets of its core people are like; it’s essential to ensure that “those wishing humanity well” hold the most powerful AI—this is Anthropic. These people would point out that Anthropic is genuinely doing much safety-related research.
I have a fun story about Chris Olah, a co-founder of Anthropic: he and I attended a very small private school in Toronto, called Abelard School; there were only 45 students total. I was in ninth grade when he was in eleventh. He introduced me to a lot of computing and mathematics concepts. One reason I began using Linux and heavily supported open-source was because of him. I truly believe that at least one co-founder of Anthropic is a good person.
The opposing view toward Anthropic holds that it has accelerated the AI race significantly, increasing the speed of AI development.
Recently, I heard an interesting viewpoint: OpenAI actually prefers to advance AI more slowly, so they didn’t allocate all resources to creating better cutting-edge models in 2024 or 2025; instead, they started working on projects like Sora, a video generation model, and several smaller initiatives. Earlier this year, with the emergence of Mythos, we began to realize Anthropic was at the forefront of innovation, as more people started using Claude. At that point, OpenAI halted many of its minor projects and began accelerating, focusing on creating very powerful models.
This is one criticism of rationalists and EAs targeting Anthropic—that the actions of Anthropic are flawed; they may believe they are doing things safer and better, yet they still partake in this competition, and their involvement has accelerated the AI race, thus increasing our dangers.
Another common critique from average people concerns Anthropic's security philosophy: “We should hold power because we are good; you should not hold power because you are not.” Many people think this way; even dictators might justify their actions similarly.
However, many would argue: if you consider yourselves good and others bad, what if we disagree? Who determines their security protocols?
At the beginning of this year, Anthropic opposed open-source, turning it into a hotly debated topic: open-source AI is more dangerous because it lacks oversight. But according to my understanding now, all the most dangerous attacks have been carried out utilizing GPT and Claude.
Therefore, you can hear their arguments; they sound plausible if you agree with their premises. However, one could also find that the correlation between their actions and the benefits for their company might exceed 90%. Are they truly advocating for safety, or are they leveraging safety and EA concepts to mask their… I don’t wish to label it as profit motives. If you genuinely believe in AI, such interests should be secondary; the genuine motivation likely concerns “who will control the future world.”
The things they do and the arguments they publicly state are quite admirable; however, the correlation between what they do and “enhancing their own power” is above 90%. How should we think about this?
I’d likely explain the critiques of those opposing Anthropic, as the PauseAI individuals might say: many people don't trust Anthropic; they feel the people within those companies are EA. You can noticeably sense that their desired outcome is to control the most powerful AI in the world. If your thoughts don't align with EA, why would you trust them?
I feel this current issue does not yet have a clear answer.
Yiwen:Do you consider your proposed d/acc approach an alternative solution?
Vitalik:I can introduce a little about the d/acc concept, which is roughly defensive, decentralized, or democratized accelerationism. There are about three points.
The first point is accelerationism. The development of technology is essential.
The second point is defensiveness. We currently need to invest more effort into protective technologies. For example, with AI hackers in play, there’s a risk they may attack our systems; we should allocate significant resources into cybersecurity; will AI also make some more dangerous viruses more likely to emerge? So we should start engaging in more antiviral measures.
Lastly, there’s decentralization or democratization. Everything we do should be about not centralizing power; our actions empower regular people, which includes open sourcing and other principles.
The next question is: how can we initiate more decentralized defenses in our world? Thus, it calls for research into digital and biological security. Actually, pandemic prevention is very crucial. Yet in the field of pandemic prevention, there are certain d/acc approaches, alongside others that are entirely non-d/acc.
For instance, I find many existing EA organizations allocate 80% of their resources to a single issue: how can we prevent AI models from aiding in the creation of more potent viruses? They seek to solve this problem within AI models. However, this is centralized defense because if other people in other countries create their models, they could very well choose not to use your technology, leaving you with that risk anyway.
One more thing: I’ve conversed with many researching antiviral topics, who currently worry about issues that are not fantastical super viruses, but rather more likely and common viruses in the short term. If that’s the case, then the restrictions you impose within AI won’t be very effective at all.
If decentralized defenses are entirely impossible, centralized defenses might be the only option; however, centralized defenses are more vulnerable, as they heavily rely on your assumptions—about who will build the most powerful models and what the dangers will look like—being completely accurate.
Thus, decentralized defenses, particularly on antiviral topics, should focus on better detection, improved filtration, and faster vaccine development, to detect every new virus promptly and initiate a vaccine quickly—these are more conventional practices, more akin to public health, rather than a “computer problem.”
It might be that many people aren't inclined toward this direction because it requires specialized knowledge or skills they lack. However, I feel that one avenue stands a better chance of success while the other doesn’t necessitate you controlling every AI in the world to succeed.
Yiwen:Currently, much of the discussion is centered on long-term risks, yet in reality, issues like deepfakes and cybersecurity present short-term impacts. For the average person, how should we understand AI safety?
Afra: Right now, the entire AI sector is encountering numerous epistemological problems, which are logically challenging. The present state feels like stepping into a kindergarten filled with wailing children, but there are no adults in the room—because, in actuality, many researchers do not understand the situation.
At the same time, massive funding continues to be poured into the construction of various data centers. Given the current pace of data center construction, this emergent effect will only grow. Previously, people believed that AI capabilities would not consistently improve, as the low-hanging fruit would eventually be exhausted. However, today’s AI is characterized by an abundance of opportunities.
What confuses— and slightly frightens—me is the serious epistemological issue surrounding AI development: researchers cannot explain in human terms or employ a mathematical methodology to clarify how powerful these AIs really are, nor can they elucidate exactly what these AIs aim to do. This is a troubling matter for me.
Recent polls also indicate that many everyday people in the US are beginning to feel fear about this topic, including Bernie Sanders; some politicians in Washington have also started to join the Pause AI movement. At the same time, the current political reality in the US is marked by severe AI populism. What this means is: Artificial intelligence is not simply a neutral technology but rather an elite technology controlled by a tech billionaire, with the goal of concentrating power and displacing ordinary people and workers. Therefore, there’s a growing panic regarding AI, compounded by apocalyptic narratives about AI, along with whistleblowing from individuals like Jacob Coxon, leading to this strange phenomenon we see now.
Vitalik:Currently one of the most important facts regarding the world and the current trajectory of technology development is that much remains uncertain. We still don’t know: first, how quickly AI will develop; second, one year, five years, or twenty-five years from now, in what domains humans will be better able to perform tasks compared to AI—what tasks will humans take on; third, whether those safety concerns can be resolved; fourth, there’s a possibility that OpenAI and Anthropic remain the most powerful AI companies, but that might change—perhaps Google will become first, or certain Chinese AI companies may catch up. So there’s a lot of uncertainty.
This also ties into numerous topics: Is an AI more like a tool, a person, or something else entirely? I agree that AI is no longer a simple tool. Nevertheless, what will our interactions with AI look like one, three years from now? If AI isn’t fully autonomous, under what circumstances may we intervene with it? How will we know what it’s doing? There are many unknowns surrounding this.
Thus, I have been unwilling to assert that my P(doom) stands at 99%, nor would I care to state it as 1% or 0. There are numerous possible occurrences. For instance, four years ago, we had no idea if the next phase of AI development would manifest through cognitive chains. A current topic of discussion involves the notion of neuralese (neuronal language), as AI still thinks in English. This allows us to study how it thinks. One of my preferences for using open-source models is that you can observe each thought process in detail. However, the concept of neuralese posits: if AI were to abandon English and begin processing in a language only it understands, our capacity to comprehend its thoughts would diminish significantly—to what extent we can only guess.
Will there be numerous parallel intelligent agents, or just one agent? How will strategies for AI safety evolve during that time?
My general thought in this field is: I believe AI safety is less likely to resemble an engineering problem and more of a political design issue. If you examine, for example, how certain government structures are designed: different parts counterbalance each other, and the goal of each component is to restrain others, thereby reducing the likelihood of significant errors happening; there are different participants conversing, with some situations where certain people shouldn’t speak too much or maintain excessive relationships; there should be communication and isolation; some segments may proceed slower while others might accelerate. All these considerations involve employing very smart yet imperfect components—humans—to create a more stable system.
A safe AI might require us to set our objectives in three different ways, potentially creating a mechanism among them to mutually limit their risks. They would also need to know when to re-inquire with users: what do they truly want? Thus, AI safety may evolve in this direction. However, if it does, it will become an inherently experiential issue: you would need to collaborate with existing AIs, understand them, and engage in tasks with them, needing to grasp the conditions under which they succeed and fail. AI safety will thus become less theoretical and more intertwined with the actions we already engage in with AI.
However, this is merely one possibility. Another important point is that the rapidity and direction of AI development over the past decade have come with many surprises. I believe we should not become overly certain about “it must go this way” or “it absolutely cannot go that way.” Keeping an open mind is paramount.
免责声明:本文章仅代表作者个人观点,不代表本平台的立场和观点。本文章仅供信息分享,不构成对任何人的任何投资建议。用户与作者之间的任何争议,与本平台无关。如网页中刊载的文章或图片涉及侵权,请提供相关的权利证明和身份证明发送邮件到[email protected],本平台相关工作人员将会进行核查。


