Currently, there are more and more Agent products, some focusing on Coding, some for daily office work, and some for emotional companionshipAlthough these products have different purposes, the underlying working principles are quite similar, which is the automation orchestration of context by Harness
This article will explain from a principles perspective how Agent tools use context orchestration to enable the model to complete tasks step by step and then output results
I will use simple language as much as possible so that everyone can understand
At the same time, we can also see what the system is preparing before the model makes each judgment: what materials have been read before, what feedback has been received in the middle, and what information has been retained afterwards may all affect the result?
What the model knows at this moment
When the model makes a request, the output can be understood as two categories:
I have enough context, and I will output the result
I do not have enough context, or I need to perform actions, then call tools (through function call)
For example, if you ask “What is user login”, the model can answer using its existing knowledge. But if you ask “Why did our website fail to log in?”, the code, running environment, and error messages of the website need to be provided separately
Pasting the error into the request gives the model a clue. To let it check the project, the model still needs to read the relevant code through tools. Even if the file is in the current directory, it still needs to find it first and then include the relevant content in the request
These instructions, dialogues, materials, and tool results provided with the request together constitute what we often refer to as “context”. For this specific task, what the model can base its judgments on largely depends on what is included here
This context will update as the work progresses. The current requirements and applicable instructions constrain the task, the retained history communicates previous events, and tool results supplement new facts. The system then organizes this content into requests sent to the model
Therefore, it is important to distinguish three areas:
What is stored in the computer
What has happened in the conversation
What the model has received at this moment
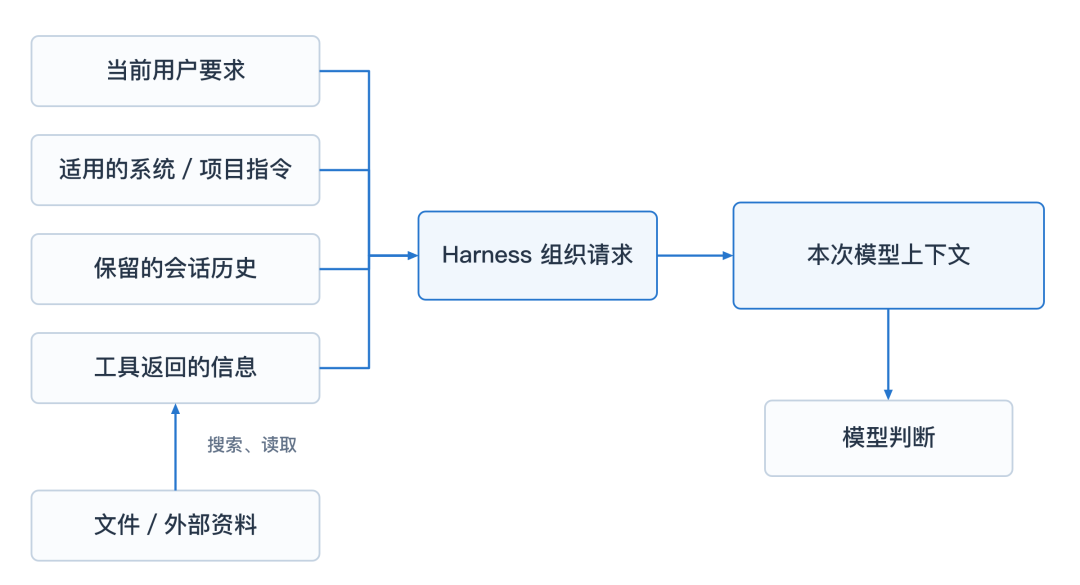 Source of Context and Request Assembly
For example, if you give AI a new file, it is usually to supplement the context for the current task. This process itself will not permanently train the knowledge in the file into the model
Here, the result produced by the Agent relies both on the model's capabilities and on the materials received (orchestrated by Harness)
How a single response turns into continuous action
The Agent will pass the operations proposed by the model to the tools, and for the results returned by the tools, another judgment needs to be made
Assuming you ask the Agent to “find out the reason for the website registration failure.” It first searches for relevant registration documents, reads the submission logic, and then performs a check. The check returns an error: the fields submitted on the page are inconsistent with what the server requires
For the errors obtained from the actual check, Harness will include these in subsequent requests, allowing the model to modify the corresponding code based on the new evidence and check again, leading to a loop: the model proposes an operation, the tool executes it, results are returned, and it enters the next judgment
From the user’s perspective, the Agent is performing a continuous task, possibly over several hours, while internally within Harness, it has gone through multiple rounds of model requests, file readings, code modifications, command executions, and so on
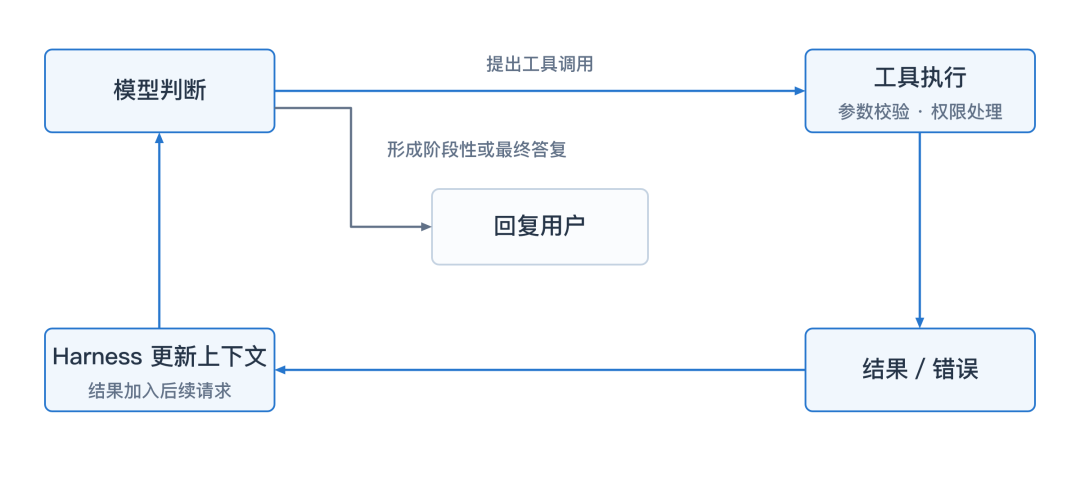 Model Judgment, Tool Execution, and Feedback Loop
The tools allow the model to take actions and also provide the model with new information
Searching allows the model to expand its dynamic context, and checking tools (or similar visual verifications) lets it know whether previous modifications are valid, thus we see that in the past year, the gap between “code generated” and “task completed” is rapidly closing
This is how the Agent, relying on various external feedbacks, continuously writes, runs, checks, and then keeps correcting
How capabilities enter the context
The more tools there are, the more instructions the model needs to understand. However, for a task, usually only a portion of them will be used
For example, if you need to process a spreadsheet, it may require calculating, organizing, and exporting. If you provide all the instructions for video editing, web design, and mobile emulators together, it will occupy the space originally meant for task materials
For Skills, Harness can use a step-by-step loading approach. First, provide the name, brief description, and location, allowing the model to judge which one is needed, then read the detailed instructions. This approach can be called “progressive loading”
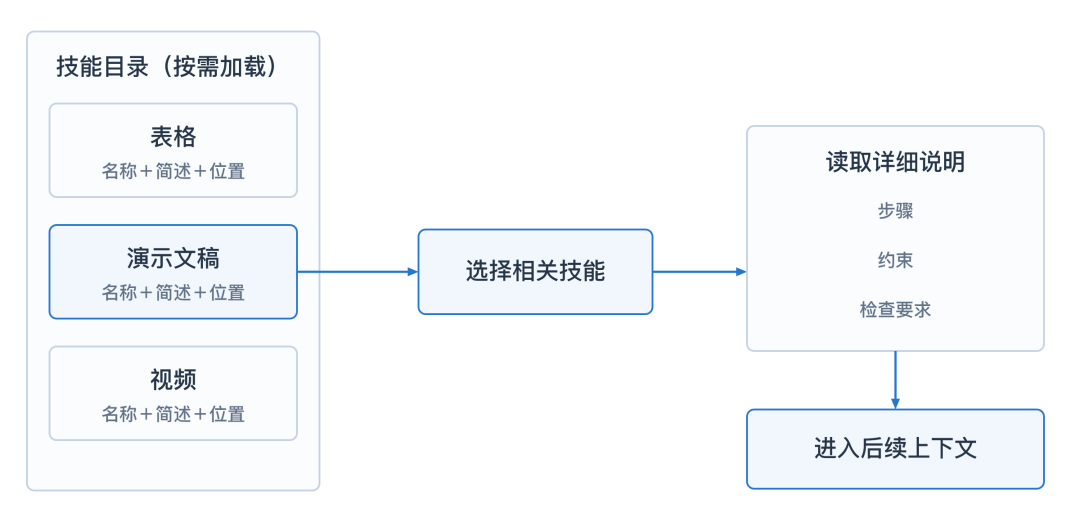 Skill On-Demand Loading
Skills provide methods for doing things: what steps to take for what situations, and how to verify in the end. Tools provide concrete operational capabilities: reading files, running programs, obtaining data. After reading the method, tools need to be called to complete the actions
For example, a Skill for creating presentations may require first determining the structure, then generating pages, and finally checking layouts. The model only knows this process after reading the instructions. Whether it can generate the file and check the page depends on the tools available
External capabilities can also be accessed through MCP. For users, it can be understood as a connection agreement that allows the Agent to discover and invoke tools provided by external services. The content returned from a single invocation then enters the task context
Plugins can organize related skills, commands, and MCP service configurations together for easy installation and management. These terms answer different questions: how to do it, what can be done, how to access, and how to distribute
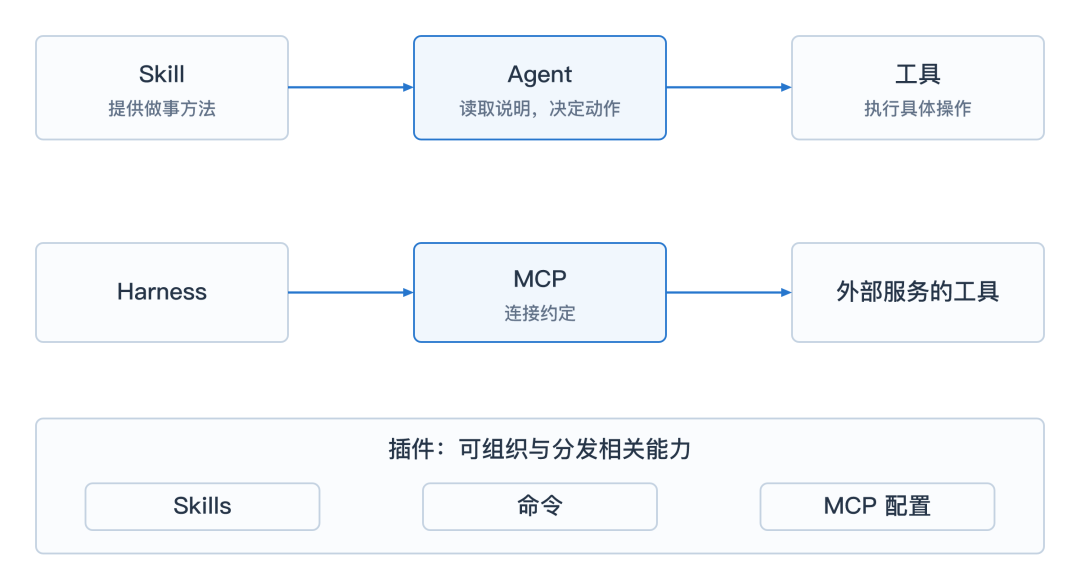 Responsibilities of Skills, Tools, MCP, and Plugins
Therefore, installing a plugin merely provides related capabilities the opportunity to participate in tasks. Specific information still needs to go through discovery, selection, and invocation to become the basis for the model's judgment
As tasks lengthen, how to maintain memory
The Agent’s continuous work will accumulate more and more information, while the model has a capacity limit on the context it can process at one time
Code searches might return hundreds of results, and commands may output lengthy logs. The same file may be read and modified many times. If everything is preserved unchanged, subsequent requests will quickly reach the capacity limit
Harness can handle this information in several ways. When tools return results, the output volume can be limited, truncated, or saved to a file, and then a preview is returned. Before subsequent requests, it can also check if history is too long, and reorganize or compress according to strategy
After compressing history, the task can continue, but the content received by the model may have changed. The old records you can scroll through in the interface may not be fully present in the current request
At this point, the distinction between files and context becomes more evident. The original logs can be saved in files, while the current context retains only the parts necessary to locate problems. If details are needed later, they can be read again through the tools
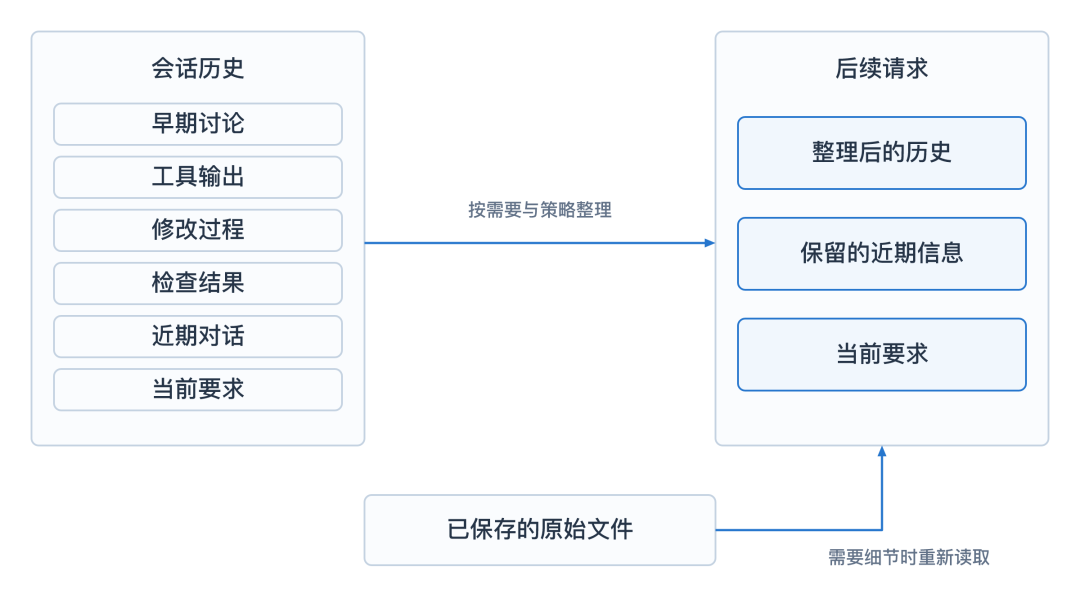 Historical Organization and File Re-Reading
“Remembering one thing” has different levels: it exists in the current context, is stored in the conversation records, and written in the project files. Only the latter two forms of storage cannot guarantee that the model will definitely use it in the next request; it still requires a corresponding recovery or reading process
For long-term tasks, progress records are therefore very useful. What the goals are, what has been done, which judgments are based on, and what is still incomplete can all be clearly saved. When taken over later, there is something to read and verify against
Writing a requirement into the project agreement serves this purpose as well: it gains the opportunity to be discovered and loaded later. Saving, reading, and compliance are still several segments that need to be independently fulfilled
How multiple Agents exchange information
Delegating tasks to multiple Agents also requires distributing information to different participants
Assuming you need to organize a research report, you could have one Agent look up product information, another verify data, and another check the conclusions. Each sub-Agent needs its own task instructions, relevant background, and available tools, and then works within its own context
Sub-Agents can work in independent sessions. What specific instructions they inherit and what materials they receive are determined by system design, task configuration, and handover methods. The content already read by the main Agent does not imply that all sub-Agents automatically know it
This division of labor can reduce the accumulation of details in the main session. The Agent responsible for data verification may read many tables, ultimately only returning numbers, sources, and problems found. The main Agent then continues to organize the report based on this
However, if the results are too brief, key evidence may be lost. If a sub-Agent simply says “There is no problem with the data,” it is very different from returning “Which data has been verified, what the basis is, and where doubts remain” in terms of aiding subsequent judgments
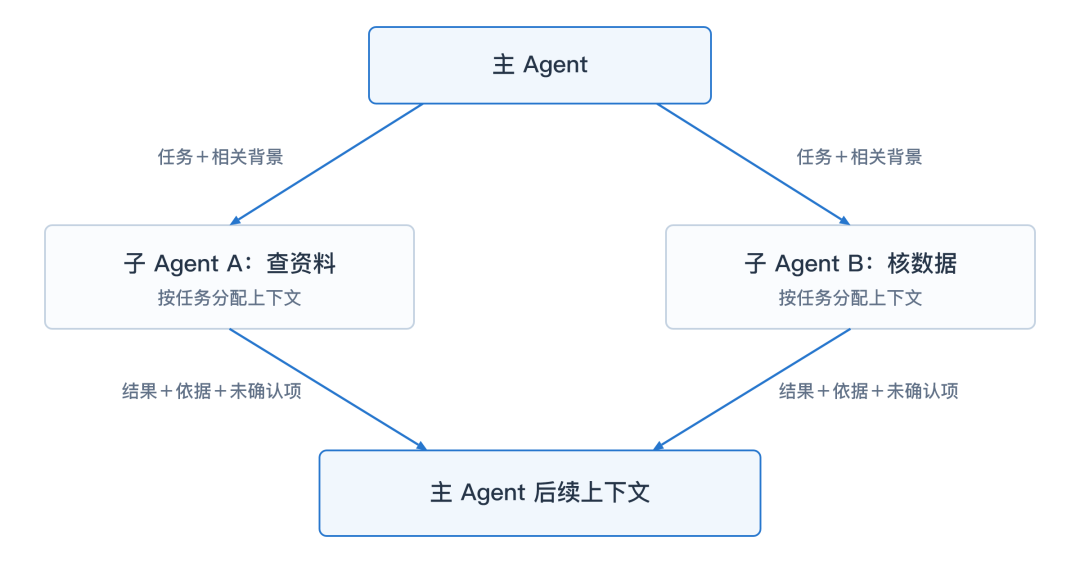 Information Handover among Multiple Agents
Thus, multi-Agent collaboration has to arrange two things simultaneously: who does which part, and what to return upon completion. Task division determines the scope of parallel work, while information handover determines whether the results can be reused
Workflows may also add structural constraints to this layer of handover. Certain steps may require fixed-format results and validate them upon submission. If the requirements are not met, specific feedback is provided, allowing the Agent to make corrections within a limited number of attempts
For instance, if it is stipulated that each conclusion must include a source, it can check whether the source field has been filled. Whether the source is reliable and can support the conclusion still requires further verification. Structured handover addresses part of the issues involved
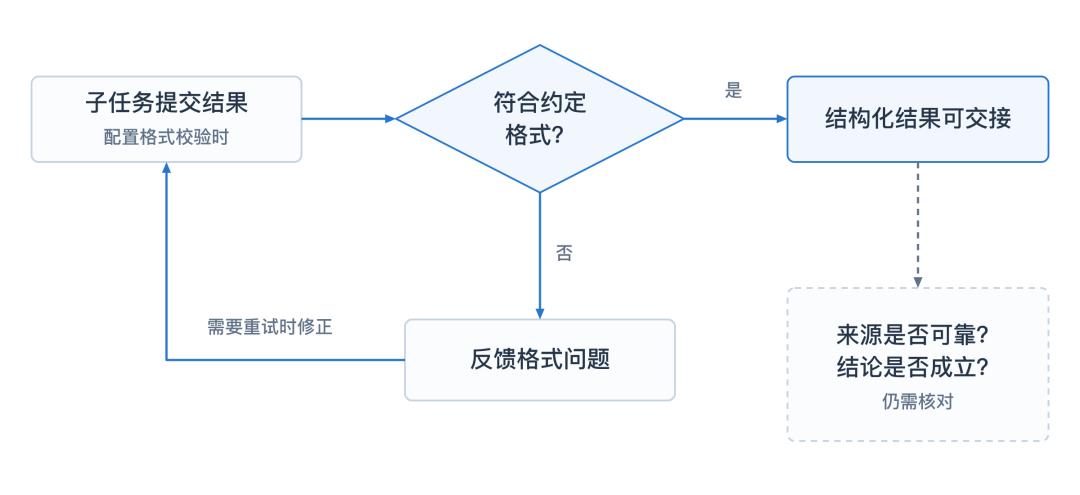 Handover Format Verification and Fact Verification
Context must also keep up with changes in the task
When the Agent is halfway through its work, new requirements you send also need to enter the subsequent processing
For example, if it is modifying the login page, and you add, “Don't change it now, tell me the reason.” The system needs to receive this input and deliver it to the Agent at the appropriate processing point while also handling operations that had already started
One way to process this is for Harness to set up queues for running inputs and background notifications. If a sub-Agent completes a task while the user adds requirements, this information needs to enter the task according to their respective rules. The order of messages will also affect the next round of judgments
There is also a pairing relationship between tool calls and tool results. Once a tool has started executing, the results returned must correspond to that invocation. The system can delay processing some messages to avoid breaking this relationship after insertion
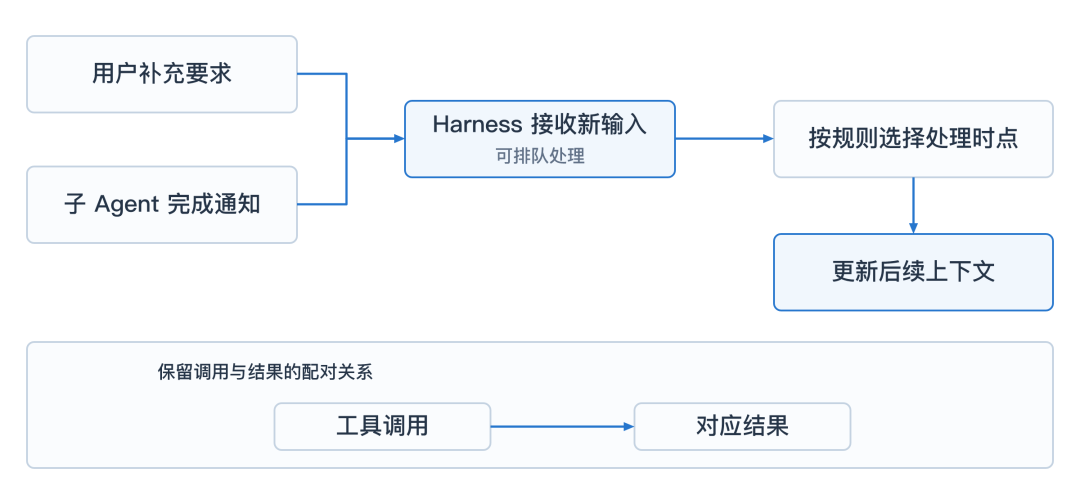 Processing Running Inputs and Call Pairing
Looking at context from this perspective, it includes both “what is available” and “the order in which things appear.” The same error message can serve as a clue to locate issues if placed before modification. If placed after, it might indicate that the previous modification didn’t solve the problem
When tasks switch to another interface, they also need to carry over these states. If connected to the same existing session, it can use the original task state; if a new session is created, a different context needs to be organized. Project files may still exist, but the trade-offs and doubts discussed in the previous section need to be carried over through records or handovers
In conclusion
All of the above are a set of common practices for “context orchestration” when the Agent is working:
First, read in the relevant materials
Allow tool results to participate in the next round of judgments
Organize history based on task length
Handover information to different Agents based on divisions of labor
These steps will be repeated continuously, as the model decides what to do next, while the system continuously organizes the information on which it bases its judgments
The sense of coherence you experience when using it is the result of the joint effects of these processes
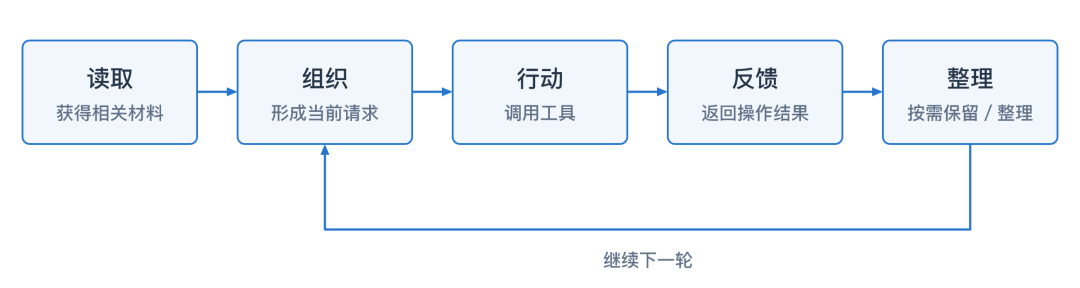 Context Orchestration Loop
免责声明:本文章仅代表作者个人观点,不代表本平台的立场和观点。本文章仅供信息分享,不构成对任何人的任何投资建议。用户与作者之间的任何争议,与本平台无关。如网页中刊载的文章或图片涉及侵权,请提供相关的权利证明和身份证明发送邮件到support@aicoin.com,本平台相关工作人员将会进行核查。


